How to move an enterprise blockchain application from pilot to production
By Jeremy Ryan, Founder & CEO · September 2026
How to move an enterprise blockchain application from pilot to production is not primarily a ledger decision. It is an operating model decision. A pilot can prove that shared records, smart contracts, and partner workflows are technically possible. Production must prove that the application remains secure, reliable, governable, supportable, and commercially useful when real organizations depend on it.
I recommend treating the transition as a formal production-readiness program rather than a larger version of the pilot. The goal is not to add more nodes or users as quickly as possible. The goal is to establish measurable evidence that the network can withstand routine growth, failed integrations, participant disputes, key compromises, smart-contract defects, and infrastructure outages without corrupting the business process.
Key Takeaways
• A successful pilot is not automatically production-ready. A pilot proves a workflow under controlled assumptions; production requires durable ownership, service levels, security controls, operational support, and recovery procedures.
• Fund production against business evidence, not transaction volume alone. The strongest case connects the shared ledger to reduced reconciliation effort, faster exception handling, improved traceability, or a contractual requirement that participants value.
• Governance must precede expansion. In a multi-party network, member admission, voting rights, data permissions, software upgrades, fee allocation, and participant exit procedures cannot be improvised after launch.
• Test degraded conditions, not just happy paths. A blockchain application must handle duplicate messages, replayed events, delayed finality, unavailable nodes, failed ERP calls, and compromised credentials.
• Immutable records change recovery. Teams generally cannot “roll back” ledger history as they would a conventional database. They need versioning, compensating transactions, clear incident authority, and a defensible audit trail.
• Roll out in cohorts. Start with a limited group of participants, real support commitments, and explicit expansion gates. Scale only after the operating model performs under live conditions.
Decide Whether The Pilot Deserves Production Funding
Separate A PoC, Pilot, And Production Service
The first decision is whether the organization has actually completed a pilot. A proof of concept usually validates one technical proposition: for example, whether several parties can write a shared provenance record. A pilot introduces selected real users, limited data, and a bounded business process. Production means the application has an accountable owner, defined availability and support commitments, documented controls, and a path to operate over time.
The staged progression matters because enterprise adoption rarely moves in a straight line. The Invesco and CCAF global enterprise blockchain report supports the lifecycle model of exploration, proof of concept, pilot or trial, and production. Each stage answers a different question. Production should not begin until the pilot has answered whether the business process—not only the decentralized ledger technology—works with actual participants.
A useful test is simple: if the platform team stopped actively shepherding each participant and transaction, would the business process still run safely? If the answer is no, the organization has a promising pilot, not a production service.
Set Funding Gates Around Business Outcomes
A production business case should state the baseline cost or risk that the application changes. Avoid vague targets such as “increase transparency.” Name the operational mechanism instead.
For instance, a supplier traceability network may aim to reduce manual document reconciliation between manufacturer, distributor, and regulator. Its production case should measure the time required to resolve an exception, the percentage of records reconciled without manual intervention, and the cost of disputes. If those measures do not improve materially during the pilot, adding participants may merely scale an expensive coordination problem.
I would require executives to approve production only when four questions have evidence-based answers:
-
What decision or workflow becomes better because participants share a ledger? The answer should identify a measurable process, such as release authorization, asset transfer, compliance attestation, or settlement confirmation.
-
Why is a blockchain architecture justified? Use it when several parties need controlled shared state and no single party can credibly or contractually act as the sole system of record. Avoid it when a centralized database with strong APIs resolves the trust and workflow problem more simply.
-
Who pays for ongoing operations? Production costs include nodes, cloud infrastructure, key custody, integration support, monitoring, audits, participant onboarding, and incident response. A pilot budget often hides these costs.
-
What event would cause the organization to stop or redesign the program? Define a kill criterion. Examples include insufficient partner adoption, no measurable reduction in reconciliation, or compliance constraints that prevent the intended data model.
Use Explicit Production Exit Criteria
There is no universal numeric threshold for every enterprise blockchain application. A high-volume supply chain network, a low-volume credential registry, and a regulated asset-transfer platform have different capacity and availability requirements. Still, vague language such as “tested at scale” creates avoidable risk.
Set thresholds that derive from the business service, then test them before go-live. The following model is a practical starting point, not a substitute for sector-specific requirements.
| Readiness Area | Production Gate | What It Proves |
|---|---|---|
| Business value | Pilot meets agreed process, cost, risk, or time objective for a defined period | The network solves a funded problem |
| Performance | Sustained and peak workload tests meet transaction completion and finality targets | Capacity matches real demand |
| Reliability | Failure testing shows critical workflows recover within the approved recovery objective | Operations can tolerate disruption |
| Security | Critical findings are remediated or formally accepted by accountable leadership | Known risks are consciously governed |
| Integration | End-to-end tests cover retries, duplicates, and partial failures with systems of record | Ledger events do not corrupt downstream processes |
| Adoption | Initial participants complete onboarding and operate against real service expectations | The network can function beyond a demo |
Fair warning: throughput is often the least useful single metric. A network can process a large number of transactions per second and still fail the business if an ERP interface posts the same shipment twice after a retry. The meaningful measure is completed, reconciled business outcomes under expected and degraded conditions.
Build Governance And Control Before Scaling The Network
Assign Decision Rights In A Multi-Party Network
Production governance is the rulebook for decisions that will eventually become contentious: who may join, who can see what, who pays for a change, and who can halt a risky process. This is especially important for consortium blockchain networks, where independent organizations share infrastructure and records but may not share incentives.
The Blockchain Council’s roadmap for enterprise blockchain pilots describes a practical path that includes governance, enterprise integration, limited pilot execution, operational ownership, and phased scale-up. The central implication is that governance is not paperwork added after coding. It shapes permissions, participant duties, and the change process embedded in the application itself.
A workable governance model usually separates these responsibilities:
| Role | Core Authority | Production Responsibility |
|---|---|---|
| Business Sponsor | Funding and strategic decisions | Owns intended business outcomes and escalation decisions |
| Network Governing Body | Member rules and policy | Approves admission, major changes, dispute rules, and member exit |
| Platform Operator | Technical service management | Runs infrastructure, monitoring, releases, backups, and incident coordination |
| Member Organization | Data and transaction accountability | Manages its users, keys, node obligations, and business data quality |
| Security And Compliance Owner | Control oversight | Reviews risk acceptance, evidence, access controls, and audit requirements |
Do not give one role unchecked authority over every function. For example, the platform operator may deploy approved code, but the governing body should authorize a change that alters shared business rules. Separating approval from execution limits both mistakes and conflicts of interest.
Design The Identity Lifecycle, Not Just Login
Permissioned enterprise blockchain systems depend on identity. Each organization, user, administrator, service account, signing key, and node should have a defined lifecycle: issuance, approval, activation, renewal, suspension, revocation, and evidence retention.
Production design should answer uncomfortable questions before they become incidents:
• Who approves a new member organization and validates its legal identity?
• How is an employee’s access removed when they change roles or leave?
• Which administrators can manage membership, deploy smart contracts, and access infrastructure?
• What happens if an organization loses control of a signing key?
• Is emergency access time-bound, logged, independently approved, and reviewed afterward?
For high-value signatures, an HSM or equivalent managed key-protection architecture may be appropriate. The correct choice depends on the consequence of key compromise and regulatory obligations. It may be excessive for a low-risk internal pilot, but it becomes harder to justify weak custody when keys authorize asset movement, regulated records, or irreversible approvals.
Map Blockchain Risks To Enterprise Controls
Security reviews often fail when blockchain controls are treated as exotic. Most belong to familiar enterprise control families, but they need blockchain-specific implementation details.
| Pilot Risk | Enterprise Control Family | Production Implementation |
|---|---|---|
| Stolen signing credential | Identity and access management | Least privilege, multifactor authentication, key rotation, revocation, admin separation |
| Unauthorized contract change | Change management | Version approvals, code review, release records, governing-body authorization |
| Sensitive data exposed to members | Data protection and privacy | Off-chain sensitive data, encrypted references, channel or permission design, retention rules |
| Node compromise or outage | Infrastructure security and resilience | Segmentation, hardened images, patching, redundant nodes, tested recovery procedures |
| Untraceable business action | Audit and logging | Correlated application, ledger, identity, and administrative logs |
| Conflicting participant actions | Operational risk management | Dispute workflow, transaction status rules, compensating transaction process |
The decision point is not whether a control exists on paper. It is whether the control works across organizational boundaries. If a member is removed from the consortium, for example, revoking portal access is insufficient if its node certificates, API credentials, or signing keys remain valid.
Engineer For Real Enterprise Failure Conditions
Test The Full Transaction, Not The Ledger In Isolation
A production transaction rarely starts and ends on-chain. It may begin in an ERP system, pass through an integration layer, invoke a smart contract, wait for finality, update a workflow system, and generate a notification or compliance record. Every handoff can fail differently.
Consider a shipment event submitted from an ERP platform. The integration service sends the transaction, then loses its network connection before receiving confirmation. If it retries without an idempotency key, the system may create duplicate ledger entries. If downstream systems assume immediate finality, they may issue an invoice before the network has settled the transaction. If a participant node is unavailable, some workflows may need to queue safely rather than reject the shipment entirely.
Test these conditions deliberately:
-
Duplicate submissions and message replays.
-
Delayed, rejected, or reordered integration events.
-
Partial outages between the application, integration layer, node, and enterprise system.
-
Contract execution errors caused by invalid or outdated reference data.
-
Member-node unavailability and recovery after missed events.
-
High-load processing combined with a node failure or database failover.
The engineering response generally includes idempotent business commands, durable queues, correlation IDs, retry policies with limits, reconciliation jobs, and clear transaction-state semantics. A user should know whether an action is pending, final, failed, or requires manual review. “Submitted” is not the same as “settled.”
Treat Smart Contracts As Controlled Production Components
Smart contracts should be tested like critical business logic, not treated as self-executing magic. Review authorization conditions, boundary values, event behavior, upgrade paths, failure messages, and interactions with off-chain services. Independent security review may be warranted where contracts authorize high-value transfers or enforce contractual rights.
Immutability creates a particular operational constraint. If a contract calculates an incorrect fee or writes a flawed status, deleting history may be impossible or inappropriate. The recovery design should specify whether the organization will:
• Issue a compensating transaction that corrects the business effect.
• Deploy a new contract version for future activity while preserving prior records.
• Pause a narrowly scoped function under pre-approved emergency authority.
• Reconcile affected off-chain systems and communicate the authoritative corrected status.
Avoid calling a compensating transaction a rollback. The original record remains part of the audit trail. The organization is correcting the business state through an additional, governed action.
Build Observability Around Business And Cryptographic Signals
A production dashboard should not stop at CPU use and node uptime. Infrastructure signals matter, but they do not show whether the business process is safe.
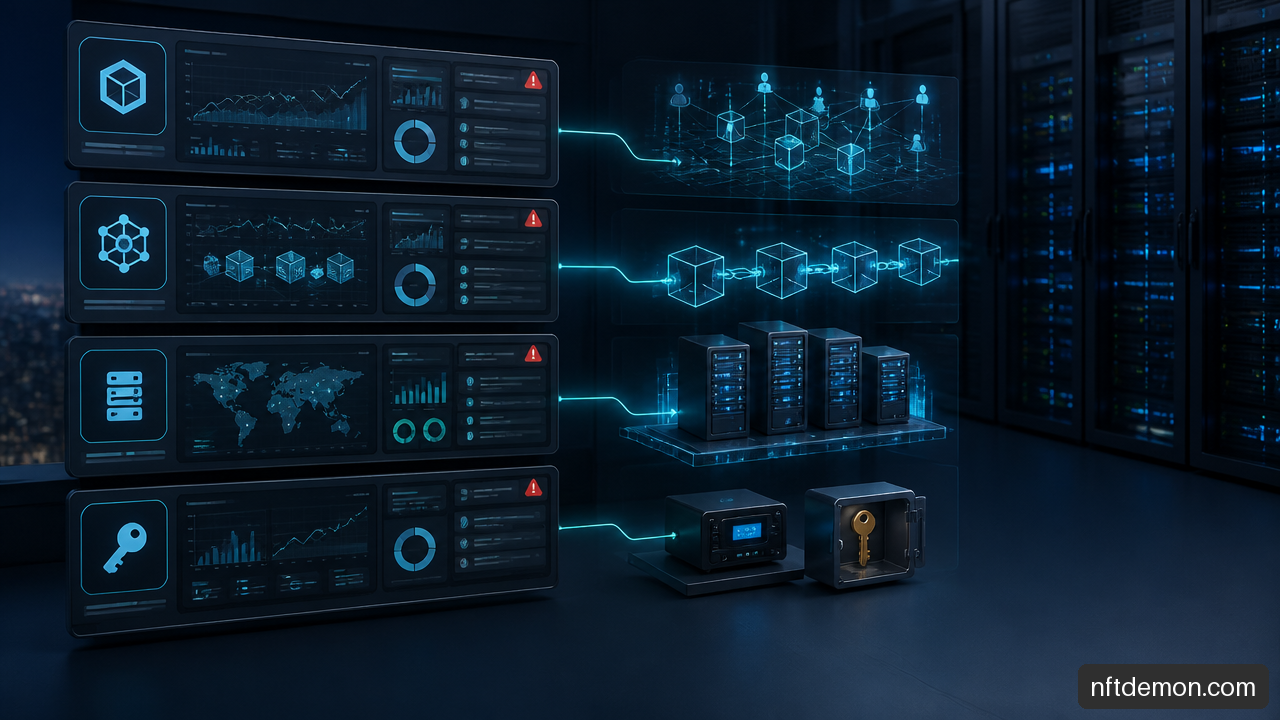
At minimum, observe four layers:
• Business signals: transaction completion rates, exception queues, dispute volumes, manual interventions, and processing time.
• Ledger signals: block or transaction confirmation behavior, finality delays, rejected transactions, contract errors, and peer synchronization status.
• Platform signals: node health, storage growth, network latency, API error rates, backup completion, and failover events.
• Identity and key signals: failed authentication attempts, privilege changes, certificate expiration, key rotation status, emergency-access use, and administrative actions.
Alert thresholds should distinguish a transient issue from an incident. A brief increase in finality time may warrant investigation. A sustained delay that prevents contractual settlement may trigger an incident commander, business communications, and a temporary workflow procedure.
Execute A Controlled Production Cutover
Make The Pilot Operational Before Calling It Production
The pilot-to-production gap is a frequent failure point because technical validation does not guarantee operational readiness. Constellation Research’s examination of the proof-of-concept-to-production gap supports the case that organizations must plan explicitly for the transition instead of assuming a successful PoC will naturally scale.
Before cutover, run a production rehearsal using the same support escalation paths, deployment approval process, incident communications, participant onboarding workflow, and backup procedures intended for launch. If the team has never restored a node, reissued credentials, or reconciled an interrupted integration in rehearsal, it should not assume those actions will work under pressure.
Use Cohort-Based Onboarding And Expansion Gates
A phased rollout reduces blast radius. Begin with participants that have strong operational readiness, stable integrations, and clear business incentives. Do not select the first cohort solely because it is politically convenient; early users will expose the process weaknesses that later members inherit.
A practical sequencing model looks like this:
-
Freeze and verify: approve the release, baseline configurations, complete security sign-off, and validate backups and recovery evidence.
-
Onboard the first cohort: issue identities, validate permissions, test end-to-end workflows, and confirm support contacts for every organization.
-
Operate under real service conditions: measure business and technical service levels, including failure handling and reconciliation effort.
-
Review expansion evidence: assess whether the first cohort meets adoption, security, performance, and operating targets.
-
Add cohorts progressively: expand by partner segment, geography, workflow type, or transaction value while preserving the ability to pause.
-
Transition to steady-state governance: move from launch command structure to recurring change, risk, audit, and member-management routines.
Expansion should pause when control quality declines. For example, if support tickets reveal repeated identity provisioning errors, onboarding more members amplifies a control failure. Fix the workflow, retrain participants, and verify the correction before continuing.
Establish Incident Response And Recovery Authority
An incident plan needs named people, decision rights, and business-safe actions. A technical team may restore a node, but only authorized business and governance leaders should decide whether to pause a settlement workflow, publish a participant notice, or issue compensating transactions.
The plan should define severity levels, notification paths, evidence preservation, participant communication, and recovery validation. It should also state what cannot be done. In many blockchain designs, an erroneous finalized transaction cannot simply disappear. That limitation needs to be understood by legal, compliance, customer-service, and operations leaders before the first incident.
Production readiness means being able to explain what happens when the system is wrong, unavailable, or under attack—not only what happens when every component behaves correctly.
Frequently Asked Questions
How Do You Know When An Enterprise Blockchain Pilot Is Ready For Production?
A pilot is ready when it meets approved business outcomes and has passed defined gates for security, integration, operational ownership, resilience, participant onboarding, and support. Functional demonstrations alone are insufficient. Production readiness requires evidence that the complete business transaction can be processed, monitored, recovered, and audited under realistic conditions.
What Are The Biggest Reasons Blockchain Pilots Fail To Reach Production?
The common causes are an unclear business case, weak participant incentives, unresolved governance, fragile integrations, incomplete security design, missing operational ownership, and unrealistic assumptions about scale. The ledger may work perfectly while the surrounding workflow remains too costly, too manual, or too difficult for partners to adopt.
What Security Controls Are Required Before A Blockchain Go-Live?
At minimum, implement strong identity lifecycle management, least-privilege access, administrator separation, secure key storage, credential rotation and revocation, smart-contract change controls, hardened node infrastructure, logging, monitoring, vulnerability management, backups, and incident response. The exact control depth depends on data sensitivity, transaction value, legal obligations, and the consequences of service interruption.
How Should Smart Contracts Be Tested Before Production?
Test contract logic with normal, boundary, invalid, and adversarial inputs. Verify authorization paths, event emissions, integration behavior, upgrade procedures, and failure handling. Where a contract has material financial, contractual, or compliance consequences, an independent security review is generally prudent. Also test compensating-transaction procedures because immutable records usually cannot be erased.
How Do You Integrate A Blockchain Application With ERP Systems Safely?
Use durable integration patterns: idempotency keys to prevent duplicates, correlation IDs for traceability, queued processing for temporary outages, explicit retry limits, transaction-status handling, and reconciliation reports. Design for the fact that ledger finality and ERP posting may happen at different times. Never assume a network timeout means the transaction failed.
What Monitoring Does A Production Blockchain Network Need?
Monitor business outcomes, ledger behavior, node and API health, storage and network capacity, authentication events, administrative actions, key and certificate status, backup completion, and integration errors. Alerts should connect technical symptoms to business impact. A failed peer is not merely an infrastructure issue if it delays settlement or blocks a regulated workflow.
How Should A Multi-Organization Blockchain Network Handle Member Exit?
The governing agreement should define exit triggers, notice requirements, access revocation, node retirement, data-retention obligations, key invalidation, financial settlement, and ongoing audit access. The network must preserve the historical record while preventing the departing participant from submitting new transactions or retaining inappropriate administrative access.
Sources And References
• Blockchain Council — Enterprise Blockchain Pilots: PoC to Production Roadmap
• Invesco / CCAF — 2nd Global Enterprise Blockchain Report
• Constellation Research — Taking Blockchain from Proof of Concept to Production
NFT Demon Holdings helps enterprises scope, evaluate, and build blockchain programs — start with a free evaluation call.
Talk through your use case
Free evaluation call — objective, constraints, and fit, before any proposal.