How to design a blockchain application for enterprise transaction volume
By Jeremy Ryan, Founder & CEO · September 2026
How to design a blockchain application for enterprise transaction volume starts with a hard question: does this transaction workflow actually need a shared ledger? If multiple organizations must reconcile records, enforce common transaction rules, and retain verifiable history without granting one party unilateral control, blockchain can be justified. If one enterprise controls every participant and every record, a conventional database with strong audit logging may be faster, cheaper, and simpler.
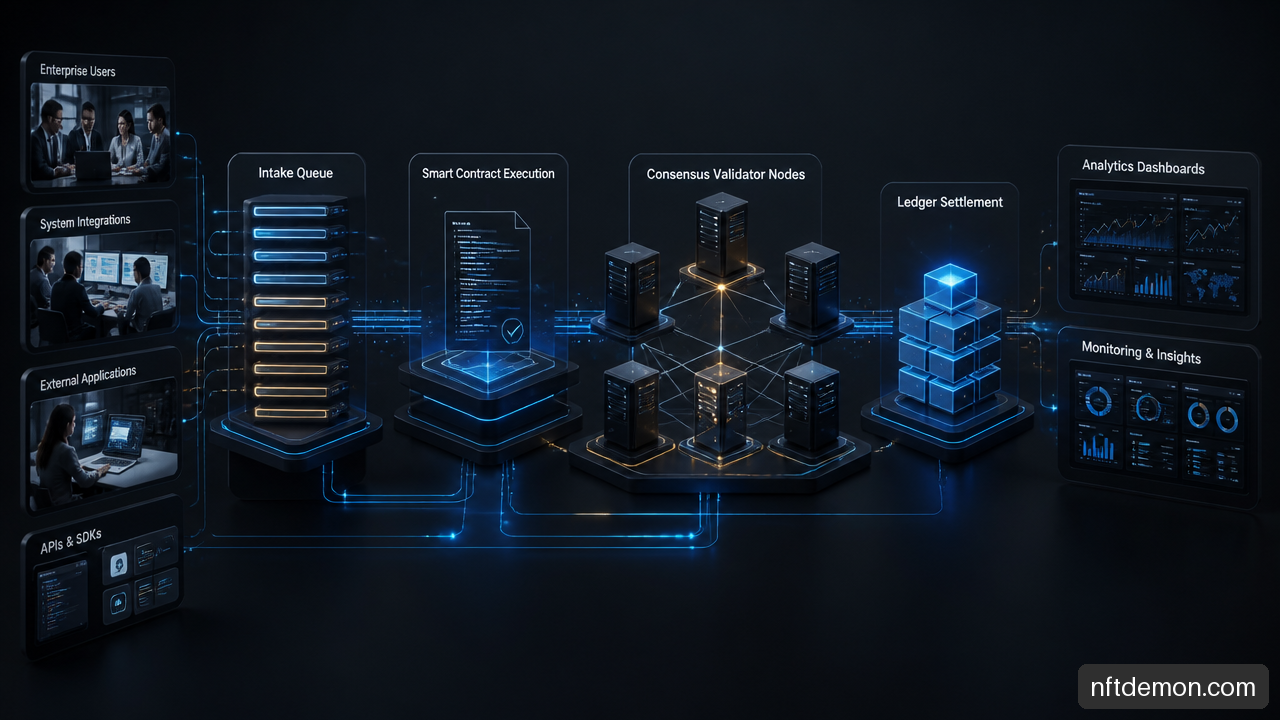
For workloads that do warrant blockchain, the design objective is not to chase a theoretical transactions per second figure. It is to deliver predictable confirmation, legally meaningful finality, controlled access, recoverability, and usable operating costs during real peak conditions. That requires treating the ledger as one service in a transaction system, not as the entire application.
Set The Workload And Trust Boundaries
Define The Transaction Before Selecting A Chain
An enterprise transaction is rarely a single ledger write. A purchase order, insurance claim, trade instruction, loyalty redemption, or supply chain handoff may involve identity checks, policy validation, document storage, signatures, settlement, notifications, and downstream reporting. The blockchain transaction should represent the point at which shared state must become authoritative.
I would begin with a transaction contract that answers the following questions:
• Who submits the transaction, endorses it, validates it, and reads its result?
• Which fields alter shared state, and which fields are merely supporting evidence?
• What response must a user receive immediately versus later through asynchronous processing?
• When is a transaction final enough to trigger delivery, payment, reporting, or legal settlement?
• What happens when the same business instruction arrives twice, arrives late, or conflicts with a previously accepted instruction?
This exercise often exposes a common design error: treating every user interaction as a blockchain write. Consider a retail returns network. A customer service representative may query a return status repeatedly, but the ledger only needs a state transition when the return is authorized, received, disputed, or refunded. Reads, document previews, and search functions belong in optimized application and indexing services.
NIST describes blockchain as distributed ledger technology that uses cryptography and consensus to maintain tamper evident records. Its discussion of blockchain terminology and permissioned governance concepts is useful because it frames the design problem correctly: a ledger is a trust and control mechanism, not an automatic performance solution.
Model Peak Demand, Not Daily Averages
Average throughput is a poor capacity target. A system handling 10 million transactions per day averages about 116 transactions per second, but that number says little about its busiest five minutes. If 20 percent of the day’s activity arrives during a 30 minute market close, campaign launch, billing window, or batch reconciliation cycle, the actual ingestion rate can be orders of magnitude higher.
Create a workload model with at least these dimensions:
| Workload Dimension | What To Measure | Why It Changes Design |
|---|---|---|
| Steady state | Typical transactions per second and read volume | Establishes baseline infrastructure cost |
| Peak interval | Highest sustained volume over 5, 15, and 60 minutes | Reveals capacity needed for predictable latency |
| Burst size | Sudden submissions within seconds | Determines queue limits and backpressure behavior |
| Transaction mix | Simple writes, contract calls, queries, attachments | Shows whether execution or storage is the bottleneck |
| Payload profile | Median and upper percentile payload sizes | Affects propagation, storage, and block construction |
| Read demand | Search, dashboards, reconciliation, audit retrieval | Prevents ledger queries from becoming the hidden bottleneck |
A practical approach is to define a service level objective, or SLO, for each stage. For example: 99 percent of valid submissions accepted by the intake service in two seconds; 95 percent committed within 15 seconds; and indexed for reporting within 60 seconds. The exact numbers depend on the business process. What matters is that the system has explicit limits rather than a vague promise of “high throughput.”
Queueing creates the most dangerous gap between benchmark claims and production behavior. If arrival rate exceeds sustained completion rate, even briefly, the queue grows. Once it grows beyond recovery capacity, user visible latency may remain high long after the original spike is over. Design admission control, rate limits, priority classes, and retry rules before the first performance test.
Choose A Trust Model And Finality Standard
For closed business networks, a permissioned or consortium model is often the practical choice. Participants are admitted, roles can be separated, transaction visibility can be controlled, and validator operations can be governed. That does not make the network automatically secure; it makes accountability and access control more explicit.
A public chain can be appropriate when public verifiability, open participation, or composability with public assets is essential. The tradeoff is less control over base layer congestion, transaction pricing, privacy, and protocol changes. A hybrid design can keep commercial records in a permissioned environment while anchoring selected proofs to a public network, but it introduces operational complexity and needs a clear dispute model.
Finality deserves equal attention. Confirmation is not always settlement. A consumer rewards program may tolerate a short confirmation delay before crediting points. A securities, treasury, or regulated asset workflow may require deterministic finality before a transfer can be treated as complete. Set the finality target from the business SLA and contractual risk, then select the consensus mechanism and operational controls needed to meet it.
Build A Throughput Architecture That Does Not Queue Itself Into Failure
Separate The Transaction Pipeline Into Services
A high volume enterprise blockchain application should avoid one monolithic service that accepts requests, executes smart contracts, orders transactions, searches the ledger, and produces analytics. Those workloads have different scaling behavior.
A more resilient decomposition usually includes:
-
Ingestion service: Authenticates callers, validates schemas, applies quotas, assigns idempotency keys, and places accepted requests into a durable queue.
-
Execution service: Runs business validation and smart contract proposal logic. It should reject invalid work before it reaches scarce ordering capacity.
-
Ordering and consensus service: Establishes transaction sequence and finality according to the selected trust model.
-
Validation and commit service: Confirms endorsements, detects conflicts, applies valid state changes, and emits durable commit events.
-
Indexing and analytics service: Creates search friendly views, dashboards, alerts, and reporting datasets without overloading ledger nodes.
The Hyperledger Fabric architecture documentation describes a permissioned architecture with modular components and distinct endorsement, ordering, and validation stages. That separation is operationally valuable because it lets architects measure where a transaction actually slows down instead of treating “the blockchain” as one opaque bottleneck.
Research on scalable enterprise blockchain architecture also supports using application service separation and microservices where it fits the operating model. The Rahasak enterprise blockchain architecture study is relevant here because it examines a microservices based approach to scalable enterprise blockchain applications.
Put Proofs On Chain, Not Every Record
Ledger storage is replicated across participants by design. Storing full documents, detailed personally identifiable information, images, telemetry, or unrestricted event streams directly on chain turns replication into a cost and performance problem. It can also complicate retention and correction obligations.
Use a data classification rule:
| Data Type | Recommended Placement | Ledger Record |
|---|---|---|
| State requiring multi party agreement | On chain | Transaction state and authorized transition |
| Sensitive business document | Controlled external repository | Hash, document identifier, access policy, timestamp |
| High volume telemetry | Data platform or event store | Periodic commitment or summarized proof |
| Personally identifiable information | Approved protected system | Minimal reference or privacy preserving proof |
| Audit evidence | Protected archive plus ledger linkage | Hash chain, event reference, signer, and time |
A hash proves that a specific file or record existed in a particular form when it was committed. It does not prove that the source data was truthful, authorized, or complete. That distinction matters. If a supplier uploads an inaccurate inspection document, anchoring its hash on chain preserves evidence of the submitted file, not the accuracy of the inspection itself. Smart contract rules, signer identity, approval workflows, and external audit processes remain necessary.
Optimize Contracts And State Access Before Adding Complexity
Smart contracts affect throughput through execution time, state reads, state writes, contention, and failure handling. The slowest contract path, not the elegant path shown in a demonstration, is what determines practical capacity.
Common bottlenecks include:
• Large fan out writes that update many records in one transaction.
• A single “global counter” or shared record that every transaction must modify.
• Unbounded loops over historical ledger state.
• Contract calls that require external network requests before completion.
• Repeated authorization checks that could be evaluated once at the application boundary and once on chain for final enforcement.
Avoid global mutable state wherever possible. For instance, if every invoice issuance increments one shared daily counter, parallel execution may serialize around that record. Allocate ranges, partition by organization or business unit, or derive identifiers without requiring a contested shared update.
Batching can increase efficiency when individual transactions are small and independent. It is a poor fit when each event needs individual finality, dispute handling, or immediate customer feedback. Batch only after measuring whether signature verification, ordering overhead, or storage writes are the actual limiting factor.
Use Scaling Patterns Only When They Match The Failure Model
Horizontal scaling is not a single switch. Partitioning, sidechains, channels, and Layer 2 systems each change how state is shared and how failures are handled.
| Pattern | Choose It When | Avoid Or Limit It When |
|---|---|---|
| Partitioned workflows | Business units or counterparties have naturally separate state | Transactions frequently require cross partition atomicity |
| Private channels | Participants need restricted data visibility | Reporting and shared reconciliation require broad access |
| Sidechain | A workload needs independent rules or isolated capacity | Cross chain settlement and operational ownership are unclear |
| Layer 2 rollup | A public chain must remain the settlement anchor while execution volume rises | Privacy, data availability, and bridge controls are unresolved |
The Ethereum Foundation explains that Layer 2 rollup designs process transactions away from the base layer and settle results back on chain, reducing execution demand on the primary network. For an enterprise using public settlement, this can be a credible scaling pattern. Fair warning: it does not eliminate the need to model withdrawal timing, proof verification, bridge exposure, and incident response.
Engineer Security, Governance, And Operational Resilience
Make Governance An Operating System, Not A Policy Document
Permissioned membership is only useful when the network has enforceable rules for admission, suspension, key rotation, software upgrades, and disputes. Define who can add a validator, what threshold approves a protocol change, how emergency actions are authorized, and what evidence is retained.
A governance design should establish:
• Legal and technical criteria for participant membership.
• Validator admission rules, infrastructure standards, and monitoring responsibilities.
• Voting thresholds for smart contract, configuration, and consensus changes.
• An emergency process for compromised credentials, defective code, or sanctioned participants.
• Data ownership, retention, disclosure, and exit obligations.
The difficult case is a member that is technically online but commercially noncompliant. Removing that organization may affect availability, quorum, access to historical evidence, and active transactions. The response plan should specify whether the participant is read restricted, write suspended, validator removed, or fully expelled, and which governance body can authorize each step.
Build Compliance Controls Into The Transaction Path
Enterprise compliance is not achieved merely because records are immutable. A compliant design usually needs identity assurance, least privilege access, protected key management, audit logs, segregation of duties, retention controls, and reviewable change history.
Keep personal and regulated data out of broadly replicated ledger state unless there is a defined legal basis and an approved handling model. Encrypt external records, restrict access through enterprise identity systems, and store only the ledger references necessary to verify integrity and sequence.
For a claims workflow, for example, the ledger might record claim identifier, authorized state transition, document hash, signing identity, and timestamp. The medical documentation or financial evidence remains in a protected repository where access can be logged and governed. This approach supports auditability without turning every validating node into a full repository of sensitive records.
Test Failure Conditions And Measure The Right Signals
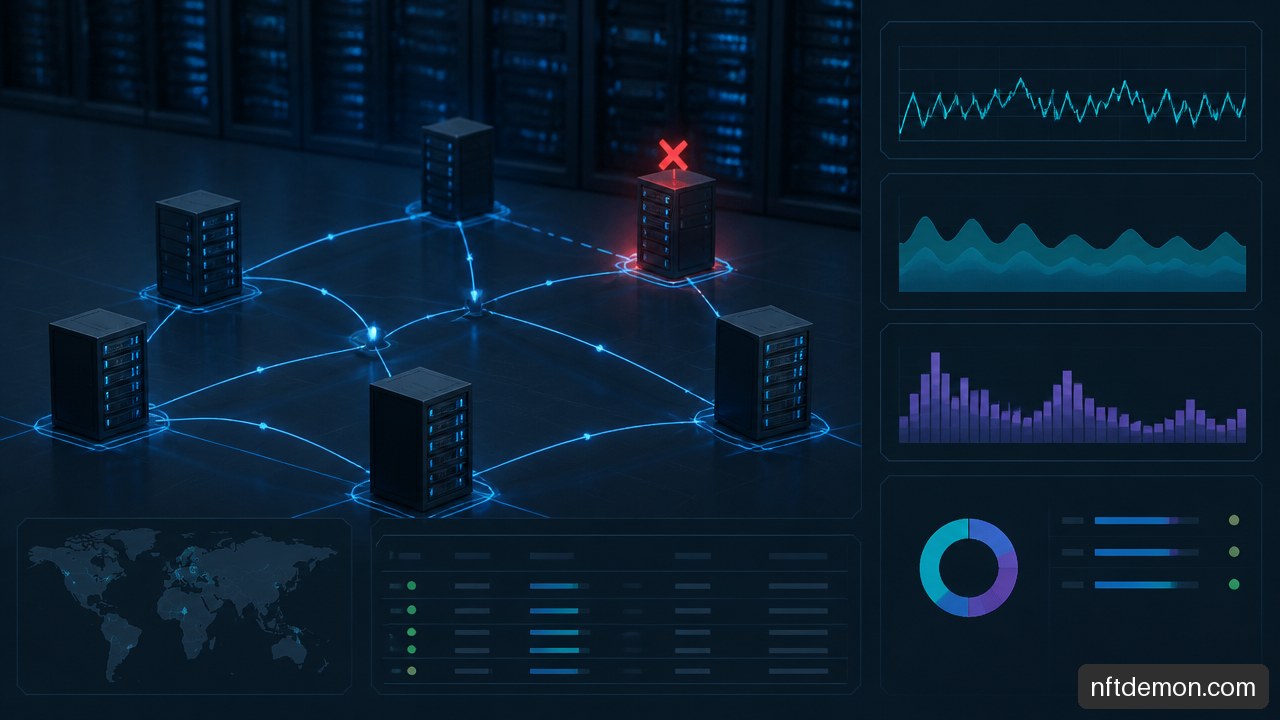
A production readiness test should be a controlled failure exercise, not just a successful load run. Run baseline, peak, burst, and recovery scenarios. Then repeat them while a node is unavailable, a dependency slows down, a queue approaches capacity, or network connectivity is degraded.
Track metrics that reveal the whole transaction journey:
| Signal | What It Reveals |
|---|---|
| Submission acceptance latency | Whether the intake tier is rejecting or queueing work |
| Queue depth and age | Whether arrival rate exceeds processing capacity |
| Endorsement or execution latency | Whether contract logic or signing is slow |
| Ordering latency | Whether consensus is the limiting stage |
| Commit and finality latency | Whether users receive timely authoritative outcomes |
| Invalid transaction rate | Whether conflicts, policy failures, or duplicate requests are rising |
| Indexing lag | Whether dashboards and reconciliation views are behind the ledger |
| Node health and peer divergence | Whether the network remains consistent through failure |
Define recovery targets as carefully as performance targets. If a node fails during a peak hour, how quickly must the network restore quorum? If an indexer falls behind by two hours, can finance close books? If a network partition occurs, should the system reject writes, permit only local drafts, or process transactions with a later reconciliation rule? There is no universal answer. The business consequence determines the safe behavior.
Finally, design an exit route. Retain portable transaction exports, schema documentation, contract source and build artifacts, participant identity records, and cryptographic verification material. Avoid a design where historical evidence can be read only through one vendor hosted interface. Interoperability is useful, but controlled migration is often the more immediate enterprise requirement.
Frequently Asked Questions
What Blockchain Architecture Is Best For Enterprise Throughput?
For a closed network of known organizations, a permissioned or consortium architecture is often the strongest starting point because it supports controlled membership, governance, and predictable operational roles. Use a public chain when public settlement or open composability is a core requirement, not merely because blockchain is being considered.
Which Consensus Mechanism Is Best For High Transaction Volume?
Choose consensus based on required finality, fault tolerance, participant trust, and governance. High volume enterprise workflows commonly favor permissioned consensus designs with fast, deterministic finality over proof of work. The correct choice depends on how many validators may fail or act maliciously and whether the business process can pause during a quorum loss.
How Much Data Should Go On Chain Versus Off Chain?
Put shared state transitions, signatures, timestamps, and integrity commitments on chain. Keep documents, personal data, media, telemetry, and large payloads in systems designed for protected storage and retrieval. Record hashes and controlled references so participants can verify external evidence later.
How Do You Size A Blockchain System For Peak Load?
Measure peak sustained demand, short burst size, transaction complexity, payload size, and required p95 or p99 confirmation latency. Then load test the entire pipeline with realistic reads, writes, retries, and downstream indexing. Do not derive capacity from the daily average alone.
How Do Smart Contracts Affect Throughput?
Smart contracts consume execution and state access capacity. Contracts that use large loops, excessive writes, shared mutable records, or external calls can reduce throughput sharply. Profile the slowest realistic transaction path and redesign state contention before adding more nodes.
When Should You Use Sharding, Sidechains, Or Layer 2?
Use them when the workload can be partitioned without creating constant cross network coordination. A sidechain or Layer 2 can isolate execution demand, while partitioning can keep unrelated business domains from competing for the same resources. Avoid these patterns when atomic cross domain settlement is frequent and the bridge or coordination model is not mature.
What Monitoring Does An Enterprise Blockchain Need?
Monitor acceptance latency, queue depth, execution time, ordering delay, commit latency, finality time, invalid transaction rates, indexing lag, node health, and certificate or key events. The key question is simple: can operations identify which stage is delaying a transaction before business users notice?
Sources And References
• NIST — Blockchain Technology Overview
• Hyperledger Fabric Documentation — Architecture
• Ethereum Foundation Documentation — Layer 2
• OSTI — Rahasak—Scalable blockchain architecture for enterprise applications
NFT Demon Holdings helps enterprises scope, evaluate, and build blockchain programs — start with a free evaluation call.
Talk through your use case
Free evaluation call — objective, constraints, and fit, before any proposal.